 systemdesign.com
Write-Behind Caching
Reduces database load; requires durable write queues and recovery logic to prevent data loss on failure.
A living reference for engineers who design systems that must work—every time.
Establish the foundational ideas that define robust system design—focusing on trade-offs, scalability limits, and reliability over fleeting trends.
See all →Learn how to construct reliable infrastructure components—caching, queues, routing, and failure handling—using real-world patterns and constraints.
See all →Design stable interfaces between services—handling retries, idempotency, and data synchronization across distributed components.
See all →Operationalize designs through observability, capacity planning, and incident response—ensuring systems remain healthy under real-world load and change.
See all →One email when something new is published on systemdesign.com. Unsubscribe any time.
Compare foundational patterns—Layered, Event-Driven, Microservices—through tradeoff tables grounded in latency, consistency, and operational complexity, not opinions.
Clear separation but tight coupling; suitable when teams align to database schemas, not business capability boundaries.
Decouples producers and consumers; introduces ordering, replay, and error-handling complexity at scale.
Enables independent deployment but demands robust service discovery, observability, and data consistency strategies.
Actionable tactics for caching, sharding, and async processing—each annotated with implementation footnotes about pitfalls (e.g., cache stampede mitigation, hot keys, event replay idempotency).
Reduces database load; requires durable write queues and recovery logic to prevent data loss on failure.
Scales reads and writes by key ranges; avoids rebalancing overhead but risks hot shards with skewed access patterns.
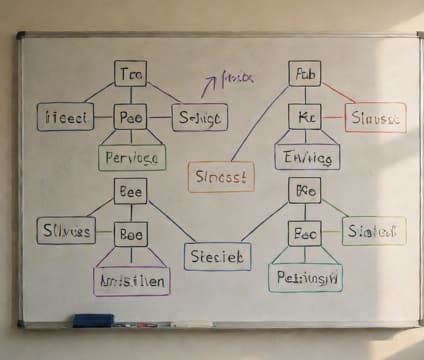
Coordinates distributed state via choreographed messages; clearer traceability than choreography but tighter coupling in the orchestrator.
Annotated breakdowns of public infrastructure decisions—e.g., how Discord routes voice traffic over WebRTC with fallback paths, or how Stripe handles payment idempotency across regions—without vendor narratives.
Filterable tables comparing databases (e.g., CockroachDB vs. Amazon Aurora), CRDT libraries, and consensus protocols—each row includes version compatibility, consensus guarantees, and known gotchas.
Compare Raft (etcd) vs. PBFT (Hyperledger) vs. Paxos variants in latency, throughput, and fault tolerance.
Match partition tolerance, consistency model (CA/CP/AP), and operator overhead against team expertise and SLA constraints.
Assess conflict resolution semantics for G-Counters vs. PN-Counters vs. MV-Reg in offline-first and multi-region apps.
Patterns submitted, reviewed, and refined by peers—each includes versioned architecture diagrams, code snippets, and peer review comments, all preserved in an immutable revision history.
Dual upstream proxies with shared sticky session store to eliminate single-point failures at ingress.
Separates schema migration execution from deployment cycles using feature flags and schema version guards.
Reduces dependency-check overhead by bundling probes and caching failure state with degraded TTL.
Guided sequences—from fundamentals (CAP theorem, consensus basics) to advanced topics (distributed tracing, state machine replication)—with quizzes, diagram exercises, and ADR templates.
Questions or ideas about systemdesign.com? Send a note and we will get back to you.
For acquisition, partnership or investment inquiries about systemdesign.com, use this form.